Showing posts with label Cloud. Show all posts

Sunday, June 16, 2013

The Clouds

I am walking in the air, and speculating about the sun.
-- Socrates, in Aristophanes' The Clouds
Self-explanatory.
What's wrong with having your head in the clouds?  For starters, you might fall into a well.  That's what happened to the ancient Greek philosopher Thales while he was gazing at the heavens.  Aristophanes ridiculed Socrates in a satire called The Clouds for speculating about abstract nonsense without understanding anything about the here-and-now.

Slightly more recently, 'The Cloud' has arrived to save us from all earthly ills.  Got a problem scaling?  Move to the cloud.  Want to reduce cost?  Go to the cloud.  Disaster recovery?  Cloud.  High availability?  Cloud.  Yet, the cloud can't really be a cure-all.  It may be appropriate for your needs, but this has to be evaluated given an understanding of how your cloud implementation will work.  If your number one problem is performance or security, the cloud is probably not going to help.

There are many 'clouds' or high-level cure-alls available to developers today.  For example, I've been learning the Spring Framework, which is a Dependency Injection (DI) framework.  DI is a form of Inversion of Control (IoC), in which object coupling is not known at compile-time but rather is determined at compile-time.  Using a DI framework, you can build interfaces, inherit classes from them, and control application flow using configuration files and annotations (like @inject).  During development, you can stick to the pure work of thought--programming, that is--without having to worry so much about the nuts-and-bolts of connecting classes.

DI frameworks like Spring are just one more layer of abstraction (or one more cloud) that let us focus on business logic rather than implementation details.  And, just like other layers of abstraction, they're a double-edged sword.  Dependency injection isn't always a great idea, such as if your interfaces are likely to change often.  Dependency information has to be stored somewhere, after all.  Enterprise frameworks tend to give you flexibility for the price of code bloat and complexity.  In my time, I've seen programming become ever more complex, but, at the same time, ever more like plumbing.  Frameworks like Spring, Rails, and .Net's Entity Framework let you quickly build applications.  But they don't prevent you from doing very stupid things if you don't know how they really work.  ORM libraries are great, for example, until you have to scale.

For this reason, I've been brushing up on my data structures and algorithms.  It's easy to think such things don't matter.  Plenty of people get by without earning computer science degrees.  And who cares if a client-side algorithm is O(N^2) when the database is orders of magnitude slower?  You might concede that algorithmic theory is worth studying only to develop certain intuitions about processing time, memory size, problem size, and algorithmic complexity, which is certainly true.  But I think it's useful to revisit data structures and algorithms once in a while to stay grounded in reality.  If you're only doing high-level plumbing, you have your head in the clouds. 

Sunday, September 9, 2012

Mapreduce and Key-Value Systems

I've been playing around with Riak (ree-ack), my first foray into NoSQL, and it's been a lot of fun. Riak is an open source implementation of Amazon's DynamoDB. It's a web-ready key-value store that scales easily. And it's a whole different world from RDBMS's. Basho has a great tutorial for getting started.

If you're a database guy like me, you're probably wondering what you can do with a key-value store. Using key-value tables is a SQL anti-pattern. Even if you get performance and scalability (which I'll discuss in an upcoming post), it's hard to see how you could do any interesting queries with a key-value system.

One thing to note is that a file system is basically a key-value store. The key is the file name and the value is the contents of the file. You can do searches on file systems, but you can't really do much querying. If your data needs are more like a file system than complex analytics, a key-value store might be right for you.

I also finally learned what the MapReduce algorithmic framework does. You may have heard of MapReduce (amongst many other new technologies) in connection with Hadoop. MapReduce will probably go down in history as one of Google's greatest contributions to computer science (along with the PageRank algorithm).

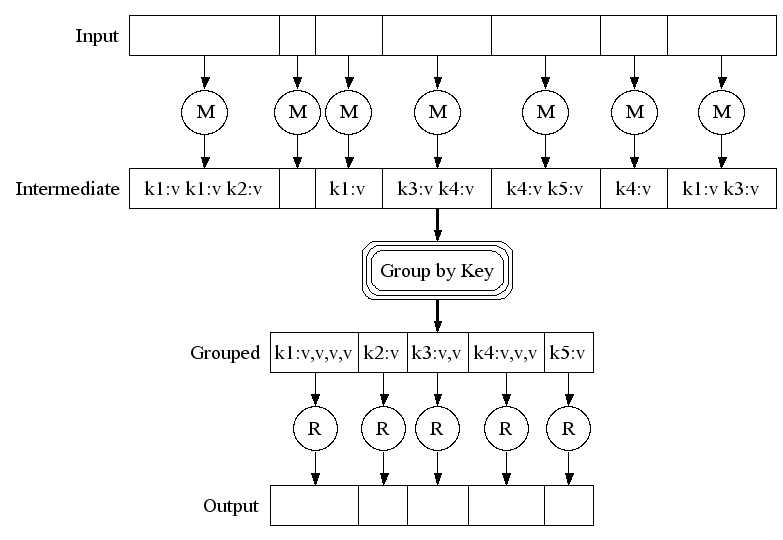
MapReduce is inspired by a functional language, LISP.  The idea is simple: take the algorithm to the data. In a highly distributed and scalable system, it's not feasible to move data to a processor in order to aggregate and slice it. You have to do any processing in-place. The way to do this is to map your keys to some kind of broader category and then run a reduce algorithm over the mapped data to pick out only the information you need.


For example, let's say your key-value store contains documents, and you want to count the number of documents beginning with the letter 'X' that contain the word 'tibialoconcupiscent'.  In this case, you would map all documents with a key like 'x*', such as 'xerophagy.pdf'.  Your reduction algorithm would simply return 1 for every case of the word and 0 otherwise. This reduction could be run on each server, a group of servers, and then all servers, returning a single (probably small) number.

This framework may seem limited, and it is. Key-value systems just aren't great for complex querying. One reason SQL has been so popular is that it allows for unlimited combinations of queries. You're limited in the ways you store data, and you have to wait for the system to write the data to disk in order to ensure consistency, but you can read the data in lots of interesting ways. That's why it's called a Structured Query Language.

(Riak does let you do some more interesting things because you can create links between different keys that define any kind of relationship between them. These links are just metadata. You can MapReduce across links, but the basic idea is the same.)

Now, where would I use Riak? There are a good number of production users already. I would think it would be best used in systems that don't require a lot of complex querying or complex data types. For instance, it could store webpages, messages, or other content. Unless you have a huge amount of data or require very fast writes, it's probably not necessary. But if you're looking to grow fast, it might be the right choice.

Sunday, April 22, 2012

Bigger Faster Stronger

Scalability is one of those words that everyone uses but few understand. It's a measure of how adding resources (typically hardware) affects performance. You can scale vertically by increasing the power of a server. You can scale horizontally by adding servers. The scalability of a system depends on how performance is defined. Martin Fowler suggests a few categories:
Expect more posts on this one
  • Response time, or the amount of time it takes to process a request
  • Responsiveness, or the amount of time it takes to acknowledge a request
  • Latency, or the amount of time it takes to get a response (this is especially important when there is no data to return)
  • Throughput, such as transactions / second
  • Load, or the amount of stress a system is under
  • Load Sensitivity, or response time / load
  • Efficiency, or performance / resources
  • Capacity, as in maximum throughput or load

Systems must be designed to scale, but what scaling means will depend upon the purposes for which a system is built. It might be tempting for database professionals to think about scalability in terms of transactions / second or the number of active accounts. But what really matters is whether or not the system is usable given an increase in transactions or accounts, and this depends upon the use for which the system was created. If we're talking about an e-Commerce system, throughput is probably more important than response time, as long as responsiveness is high. If we're dealing with a manufacturing system, we'll probably be most interested in throughput.

It's important to design systems to be scalable. The Internet has increased adoption rates to unprecedented rates. Consider Instagram, which has 30 million users after 2 years. Draw Something had 36 million users in three weeks. Scalability is a prerequisite for virality.

In the case of N-tier applications which have a Service-Oriented Architecture, it's usually easy to add hardware to the web and application servers. Load balancers and web farms can take care of extra load by distributing it evenly across a number of servers. The real problem is, as always, the database layer.

You can't just add servers to the database layer, because databases must be architected across multiple database servers. Concurrency adds to the difficulty, as database transactions must be ACID (atomic, consistent, isolated, and durable). In other words, you have to manage updates to multiple servers, making sure that an update to Server 2 does not depend on Server 1.

Lighting bolts make it faster
I thought the Cloud might be the solution to database scalability, but Microsoft Azure currently supports databases of only 150 GB in size. In talking with Microsoft consultants, they recommend 'sharding' databases. This means having a master database that directs transactions to the appropriate database server. For instance, all transactions dealing with North American accounts should go to Server 1, South America to Server 2. Sharding adds a layer of abstraction and a layer of complexity, and it requires duplication of database schema, but it's an increasingly popular approach.

Another option is Oracle's RAC system or Microsoft's MatrixDB, which has basically been ported to Azure. I'm skeptical that MatrixDB will make it in to the next edition of SQL Server (2012 has AlwaysOn, which is close, but the mirrors are read-only). In RAC or MatrixDB, databases are replicated across multiple servers and a load balancer directs reads and writes to the server with the least load. Changes are replicated asynchronously between database servers. Still, there are limitations to the size of databases for which this would be feasible.

Relational databases are great up to a certain size (though this is growing, thanks to SSD's and improved caching). It's hard to say exactly what this size is. In the end, scalable databases adhere to principles of normalization and partitioning. After a certain amount of data, RDMS's will be of no use, and NoSQL solutions are the answer to a different problem. Are you ready to scale?
Related Posts Plugin for WordPress, Blogger...