Showing posts with label NoSQL. Show all posts

Sunday, May 19, 2013

Taking Another Look at SQL

The man; the mystery
Many people think they can do without RDBMS's.  But before you say goodbye to the relation forever, I think it's useful to recall the problem for which it was meant to solve.  We've become so used to RDBMS's that their benefits may too close to us to be seen clearly.  I have a new-found appreciation for them after reading Ted Codd's 1981 Turing lecture.

Recall that prior to RDBMS's were DBMS's.  If you had data that you needed to persist, you had two options: file-based storage or hierarchical databases like IBM's IMS.  In either case, data storage code was highly coupled with application code.  If you wanted to add a new field to your customer information in IMS, for example, you had to update all your pointers referencing customer information.  If you wanted to query your data, you had to bake your searches in from the beginning.

One of the main things RDBMS's provided was an abstraction layer between your application code and your data model (your data structures, operators, and integrity rules).  Want to add a new persisted field?  No problem!  Programmers could be more productive by focusing on business logic rather than storage details.


Still, by using a relational data model, RDBMS's do shape application code.  They let you query data in ways you had never planned, but you need to have a system to get your data in and out of them.  Hence the need for ORM.  One of the benefits of NoSQL databases like MongoDB is that they have an incredibly simple key-value-based data model.  You can ignore ORM completely, and thus spend even less time thinking about storage.  (There is a trade-off, of course.  Querying the data becomes more difficult).

If there is a reason to go NoSQL, it's programmer productivity.  NoSQL made a lot of sense for Google in the early 2000's due to the cost of hardware. As the cost of processing power continues to decrease, the need to use commodity hardware should not be a central reason to turn to NoSQL for most people.  Programmer productivity should.

In short, I see the move from DBMS's to RDBMS's and now back to NRDBMS's (non-relational database management systems) as part of a broader trend to abstract away details and work on the interesting stuff.  Just as with garbage-collection in OO languages, we're always looking to get closer to the pure space of thought,

Sunday, January 27, 2013

The CAP Theorem

Life is full of tradeoffs.  I once had an ancient barber (and man of few words) who kept a sign on the wall.  It said: "Fast, Good, or Cheap: Pick Two."  After many fast, cheap, and bad haircuts, I've found that this aphorism applies not only to coiffuring.

You can find tradeoffs like this anywhere you look.  When it comes to data storage, the tradeoff is between consistency, availability, and partition tolerance.  According to a famous conjecture by Eric Brewer--and later formally proven by Seth Gilbert and Nancy Lynch--you can only pick two of the three.

In any production environment, you have distributed data sets stored on a number of different nodes.  The edge case is one node, but it's most likely (I hope) that you have data distributed across two or more.  MS SQL Server, for example, lets you easily set up replication across two nodes in an active-passive model (Microsoft calls this mirroring).  If one node goes down, the other takes over.  When the first comes back on, it syncs with the second.  Amazon's Dynamo replicates over N nodes, providing a highly configurable and fault-tolerant environment.  If a node goes down, its data will be replicated to others.  But you don't have to go that far.  A tape backup could be considered a high-latency node and might be sufficient, depending on your needs.

Before talking about the tradeoffs, let's consider a few definitions. 

Consistency refers to the degree to which nodes in a distributed system agree about a data set.  In a 100% consistent system, all nodes see the same data at the same instant.  Consistency could be measured as a fraction of the number of nodes.  Given 5 nodes where 4 agree, you'd have 80% consistency.

Availability refers to the responsiveness of a system.  In a 100% available system, all requests will receive responses.  Availability is usually called uptime and is measured in units of time.  In order to increase availability, you typically increase the number of nodes in your network.

Finally, partition tolerance refers to the ability of the system to handle disruptions in network communication between nodes.  A 100% partition tolerant system would be able to work without any network communication.  That is, it wouldn't be a distributed system.

From these definitions, you should be able to guess at why you can't have all three.  Rather than offering a formal proof, I think it's easiest to see why by considering each combination in turn.


A consistent and available system (CA) will always give you the same answer, and it will always respond to requests.  However, it won't be distributed.  The token CA system is a single database, whether it be PostgreSQL or Redis.  As long as you use some kind of transaction isolation level, you don't have to worry about inconsistencies in your data, and you don't have to build any application logic to shard data to different databases.  As your data grows, however, this system may not suffice.

A consistent and partition-tolerant system (CP) is a distributed system that enforces requirements regarding the number of nodes that must be updated in order for a write to be considered successful.  HBase and MongoDB do this, for example.  If nodes go down, they will replicate data to other nodes.  However, because they have consistency guarantees, it is possible that they may refuse reads or writes in the event of a network failure.  For example, if you have a three-node system that requires two nodes to agree, and you have a network error in which one node is separated from the other two, that node will not be available.  Any clients connecting to it will be denied service.

Finally, an available and partition-tolerant system (AP) replicates data all over the place so it can't possibly guarantee consistency.  For example, CouchDB and Riak embrace fault-tolerance over consistency.  The idea is that they will be eventually consistent, but they might not be consistent immediately following a write or network outage.

Now, almost any system can be CAP if you're willing to wait.  The tradeoff only exists when we're talking about a single instant.  If a system takes only a few ms to become consistent, this may be sufficient.  The Internet's DNS will eventually be consistent, but there are no guarantees about how long this will take.  Riak lets you tweak the number of nodes that must agree before a read or write is considered successful.  Still, in a sufficiently large system, you may not be able to wait that long.

Diving into the NoSQL universe may be daunting, but a big part is determining where you fall in the CAP spectrum.  Even if you're not considering a NoSQL database, I think it's useful to understand these tradeoffs.  Are there any other tradeoffs facing distributed data solutions?

Monday, October 29, 2012

Polyglot Persistance

There's been a lot of breathless optimism surrounding the NoSQL movement, as well as some bashing of the SQL-based RDMBSes that have held dominance for the last 40 years. The very name 'NoSQL' might suggest that there's no need for SQL any longer.

Martin Fowler and Pramod Sadalage provide some much-needed perspective in their new book SQL Distilled. They don't see Oracle or SQL Server going anywhere any time soon. There are three main reasons for this. First, SQL has forty years of production experience. Big banks are not going to jump to Hadoop for their transactional systems. Second, it's easy to find programmers with SQL experience. Not so for NoSQL. Third, and perhaps most importantly, NoSQL and SQL are meant to solve different problems.

Fowler and Sadalage suggest two main reasons for going NoSQL: programmer productivity and data access performance.

Column-oriented and document store NoSQL databases can be more productive for programmers because they can store objects as JSON. There is no need for ORM mapping, which has been called the 'Vietnam of computer science.' Of course, many problem domains require too many or too complex of relationships between objects to allow for this.

The main reason NoSQL databases were created was scaling. Companies like Amazon and Google pioneered NoSQL because they had way too much data to store in SQL databases. Frankly, I don't think very many companies need to worry about scaling to Google size, or they can cross that bridge when they get to it.

One of the things Fowler and Sadalage emphasize is that we don't yet have enough experience to even say when we should choose NoSQL over SQL. Still, they point to a storage architecture that takes advantage of the strengths of all systems. They call this polyglot persistence.


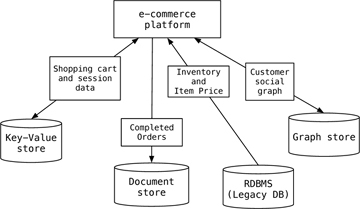
For example, in a eCommerce system, a shopping cart could be served by a key-value store like Riak; the orders and products could be an OLTP database like Oracle; order history could be in a document store like MongoDB; and customer suggestions could be maintained by a graph database like Neo4j. Of course, we could add to this a warehouse using Pentaho or a logging system using a column-family store like Cassandra.

The important thing is to gain familiarity with these products and to do POC's demonstrating the strengths and weaknesses of different approaches. For instance, I like the idea of a polyglot approach, but this puts a lot of pressure on the DBA's. In large organizations, you often have a split between developers, who know what needs to be done, and DBAs, who have the power to do it. Maintaining a number of data stores isn't for the faint of heart.

On that note, I'll be working on putting some MongoDB into practice with Python, Django, and a bunch of other things I don't know anything about. More to follow...

Sunday, October 14, 2012

HBase: A Column-Family Store

The next NoSQL database in my whirlwind tour is Apache HBase, a column-oriented database. Riak was a simple key-value database, which mapped an object it knew nothing about to a bucket/key combination. Its job was just to make sure the data was replicated consistently in a highly fault-tolerant manner. HBase schemas, on the other hand, are made up of tables, which are dictionaries of dictionaries. It gives you more granularity and schema control, but it's still dumb about the values of its key-value pairs.

For SQL developers, HBase terminology will not make much sense at first. The large objects are tables, which are made up of key-value pairs consisting of row keys and column families. The column families are, in turn, collections of key value pairs. A table is not a group of relations, nor are there any guarantees that one row will look much like another.

An HBase table

The value of this system is that you get another layer of granularity over a key-value store like Riak. You have a bunch of stuff (a table of rows), which has a couple broad characteristics (a row of column families). Listen, these NoSQL database systems are not all that different from each other. Which one is right for you will depend upon 1) your other applications, 2) your size needs, 3) your performance needs, and 4) your fault-tolerance needs.

For example, HBase cannot read until one client succeeds in writing to all replicated instances. Riak can be tweaked so that writes are successful when only one node has been written to, so it should be faster (though it's hard to find any data on these things--you'll have to do the POC yourself). HBase is best when you have a lot of data and need to run MapReduce. Riak is right if you need 99.999% uptime.

For me personally, HBase was a pain in the ass to set up. I'm not a Linux pro, and HBase isn't really meant to be run in a single instance on a crappy laptop, but this was a real turnoff. MongoDB, Riak, and PostgreSQL were all pieces of cake to set up. So why do it?

One reason is that HBase is part of an ecosystem of tried-and-tested enterprise applications, like the Hadoop Distributed File System and the query language Hive. Its users include Facebook, Twitter, and Yahoo! (Google uses its own BigTable.) There's a large community of users to go to with questions.

Still, HBase has the flavor of many Open Source systems that grew out of a matter of necessity of scaling fast on commodity hardware. I'll be interested to see what Microsoft does with Hadoop and HBase. Call me a Microsoft fan-boy, but I think their integration of technologies is often very good, and it takes time to work out the kinks in a new platform. The first iPhone was a piece of junk. It takes a few iterations for a technology to mature and solve the problems it's designed to solve.

Links:
-Check out this nice comparison of Cassandra, MongoDB, CouchDB, Redis, Riak, HBase, Membase, and Neo4j

Sunday, September 9, 2012

Mapreduce and Key-Value Systems

I've been playing around with Riak (ree-ack), my first foray into NoSQL, and it's been a lot of fun. Riak is an open source implementation of Amazon's DynamoDB. It's a web-ready key-value store that scales easily. And it's a whole different world from RDBMS's. Basho has a great tutorial for getting started.

If you're a database guy like me, you're probably wondering what you can do with a key-value store. Using key-value tables is a SQL anti-pattern. Even if you get performance and scalability (which I'll discuss in an upcoming post), it's hard to see how you could do any interesting queries with a key-value system.

One thing to note is that a file system is basically a key-value store. The key is the file name and the value is the contents of the file. You can do searches on file systems, but you can't really do much querying. If your data needs are more like a file system than complex analytics, a key-value store might be right for you.

I also finally learned what the MapReduce algorithmic framework does. You may have heard of MapReduce (amongst many other new technologies) in connection with Hadoop. MapReduce will probably go down in history as one of Google's greatest contributions to computer science (along with the PageRank algorithm).

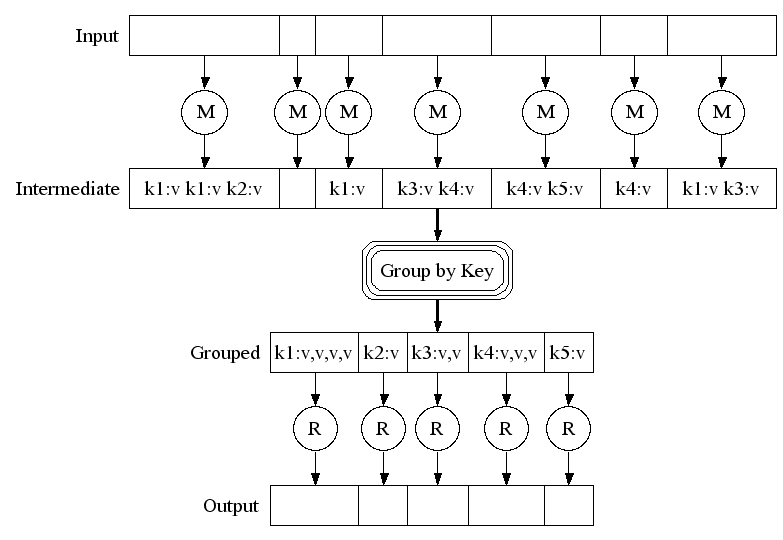
MapReduce is inspired by a functional language, LISP.  The idea is simple: take the algorithm to the data. In a highly distributed and scalable system, it's not feasible to move data to a processor in order to aggregate and slice it. You have to do any processing in-place. The way to do this is to map your keys to some kind of broader category and then run a reduce algorithm over the mapped data to pick out only the information you need.


For example, let's say your key-value store contains documents, and you want to count the number of documents beginning with the letter 'X' that contain the word 'tibialoconcupiscent'.  In this case, you would map all documents with a key like 'x*', such as 'xerophagy.pdf'.  Your reduction algorithm would simply return 1 for every case of the word and 0 otherwise. This reduction could be run on each server, a group of servers, and then all servers, returning a single (probably small) number.

This framework may seem limited, and it is. Key-value systems just aren't great for complex querying. One reason SQL has been so popular is that it allows for unlimited combinations of queries. You're limited in the ways you store data, and you have to wait for the system to write the data to disk in order to ensure consistency, but you can read the data in lots of interesting ways. That's why it's called a Structured Query Language.

(Riak does let you do some more interesting things because you can create links between different keys that define any kind of relationship between them. These links are just metadata. You can MapReduce across links, but the basic idea is the same.)

Now, where would I use Riak? There are a good number of production users already. I would think it would be best used in systems that don't require a lot of complex querying or complex data types. For instance, it could store webpages, messages, or other content. Unless you have a huge amount of data or require very fast writes, it's probably not necessary. But if you're looking to grow fast, it might be the right choice.
Related Posts Plugin for WordPress, Blogger...